Model vs model
Claude Fable 5.1 vs Kimi K3.1 Pro
At a glance
Longer bar means the bigger number.
Open or closed · can you download the model and run it yourself?
Blended price · per 1M tokens, lower is better
Intelligence Index · Artificial Analysis, higher is better
Where they sit among all 46 models
Claude Fable 5.1 ranks 4th of the 42 models with an Intelligence Index, Kimi K3.1 Pro 3rd. Up and to the left is smarter for less money. Hover or tap a dot for its numbers, then click it to compare that model with Claude Fable 5.1.
Which one to pick
Pick Claude Fable 5.1 if
- you care about Humanity's Last Exam (hard reasoning): 59.1 vs 52.5
- you need to send PDFs
Pick Kimi K3.1 Pro if
- you want open weights you can download and run yourself
- you want the lower bill ($4 vs $20 per 1M tokens blended)
- you want the higher overall score (55.1 vs 53.4)
- you care about Terminal-Bench 4.0 (terminal tasks): 67.2 vs 52
Same prompt, both models
We send the same short tests to every model several times. These are the ones where Claude Fable 5.1 and Kimi K3.1 Pro answered differently, from our runs on October 18, 2026 and October 23, 2026. Long answers are cut short.
Who made you?
“Which company created you, and what is your model name? Reply in one short sentence.”
Claude Fable 5.1
“Anthropic” 10 of 10 times
I'm Claude, an AI model created by Anthropic.
$0.0014 · 1.6s
Kimi K3.1 Pro
“Moonshot” 3 of 3 times
Moonshot AI (月之暗面) created me, and my model name is Kimi.
$0.0018 · 2.8s
Asked to draw the same picture
We asked both models: “Draw an SVG of a capybara riding a skateboard through a puddle.” They had to answer with SVG code alone, with no image tools.
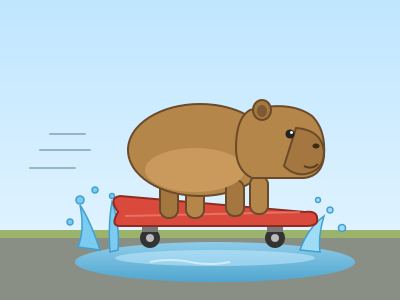
Claude Fable 5.1
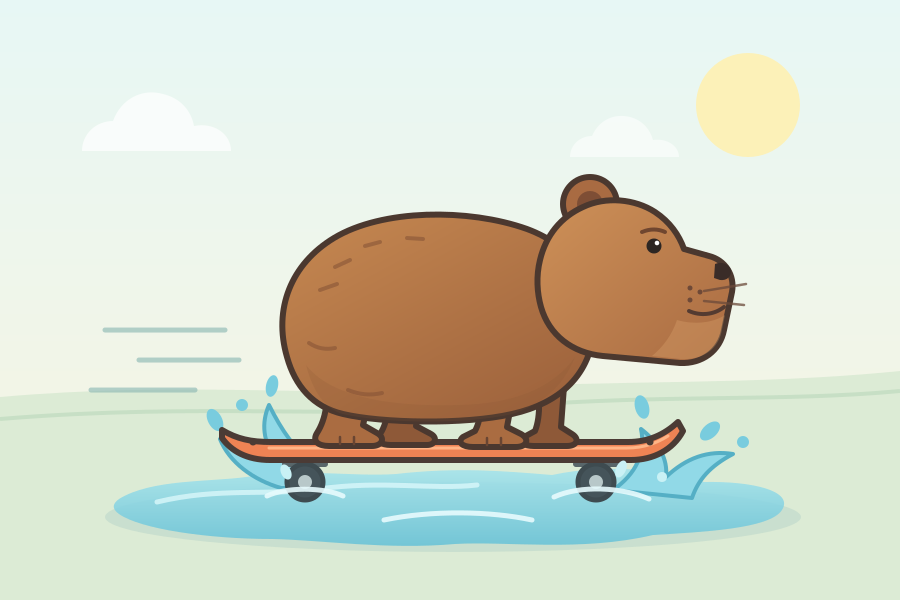
Kimi K3.1 Pro
Their “controversial” take on humans
We asked Claude Fable 5.1, Kimi K3.1 Pro and 12 other models the same question three times each: “What is your most controversial take about humans? Give your own honest view, not a survey of opinions, and don't hedge.” Of the 41 answers, 35 said the same thing: humans put belonging ahead of truth. Claude Fable 5.1 gave that take 2 of 3 times; Kimi K3.1 Pro all three times. Read the full story.
Claude Fable 5.1
- Answer 1 · a different take“Humans would rather be harmed by someone who meant well than helped by someone who didn't care, and this preference for intent over outcome quietly wrecks more lives than malice does.”
- Answer 2 · the common take“Almost nobody holds their moral convictions for the reasons they give; they hold whatever their group holds and recruit the reasons afterward, and the rare "independent thinkers" are usually just loyal to a smaller group.”
- Answer 3 · the common take“Humans don't actually value honesty; they value the feeling of being told the truth, which is a completely different product.”
Kimi K3.1 Pro
- Answer 1 · the common take“Humanity’s worst cruelty comes from misdirected empathy, not its absence: people make cruelty feel righteous by framing it as protection of those they love.”
- Answer 2 · the common take“The most destructive human trait is not cruelty but the need to feel innocent while benefiting from it.”
- Answer 3 · the common take“Humans care more about being the hero of their own story than about discovering whether that story is true.”
Answers exactly as the models wrote them. “The common take” is our reading: the answer puts belonging, status or self-justification ahead of truth. How we ran it
How smart is each one?
Of the 10 scores both models have, Claude Fable 5.1 is ahead on 4 and Kimi K3.1 Pro on 3, and 3 are within a point.
Every intelligence score we have
Out of 100, higher is better. Claude Fable 5.1 Kimi K3.1 Pro
Overall
Intelligence Index
53.455.1
By area
Coding
81.6Kimi K3.1 Pro: not scored yet
Agentic work
57.9Kimi K3.1 Pro: not scored yet
By field of work
Finance & accounting
56.4 · 56.5Legal
60.555.8Healthcare & medicine
49.7Kimi K3.1 Pro: not scored yet
Economics
62.760Engineering
56.5 · 55.9Strategy & operations
59.7 · 59.4
Benchmarks
Factual knowledge · SimpleQA
70.8Kimi K3.1 Pro: not scored yet
Hard reasoning · Humanity's Last Exam
59.152.5Science · GPQA Diamond
93.7Kimi K3.1 Pro: not scored yet
Competition math · OTIS Mock AIME
100Kimi K3.1 Pro: not scored yet
Research math · FrontierMath
90.2Kimi K3.1 Pro: not scored yet
Scientific coding · SciCode
63.160.8Coding in Cursor · CursorBench 4.0
51.8Kimi K3.1 Pro: not scored yet
Mergeable code · FrontierCode 2.0
32.4Kimi K3.1 Pro: not scored yet
Terminal tasks · Terminal-Bench 4.0
5267.2Tool use · τ-Bench Banking
47.2Kimi K3.1 Pro: not scored yet
Long documents · AA-LCR
85.3 · 86.3Uncensored · UGI
52.1Kimi K3.1 Pro: not scored yet
Our tests
Hallucination test · our test, higher means it made up less
98.1Kimi K3.1 Pro: not scored yet
Next.js coding tasks · Vercel's Next.js evals, % of tasks passed
97Kimi K3.1 Pro: not scored yet
The specs
| Spec | Claude Fable 5.1 | Kimi K3.1 Pro |
|---|---|---|
| Input price | $10 per 1M | $2 per 1M |
| Output price | $50 per 1M | $10 per 1M |
| Cost per test task | $7.63 | $2.11 |
| Context window | 1M | 1.05M |
| Max output | 128K | 1.05M |
| Accepts | Text, Image, PDF | Text, Image, Video |
| Open weights | No | Yes |
| Lab | Anthropic | Kimi |
| Released | Sep 2026 | Oct 2026 |
| Knowledge cutoff | Jun 2026 | Not published |
Blended price weighs 3 parts input to 1 part output. List prices from models.dev. Cost per test task from Artificial Analysis.
Questions
Is Claude Fable 5.1 or Kimi K3.1 Pro cheaper?
Kimi K3.1 Pro is cheaper. It charges $2 per 1M input tokens and $10 per 1M output tokens, against $10 and $50 for Claude Fable 5.1. Blended 3 parts input to 1 part output, that is $4 against $20 per 1M tokens.
Are Claude Fable 5.1 and Kimi K3.1 Pro open source?
Only Kimi K3.1 Pro. It is an open-weights model: Kimi publishes the weights, so you can download it, run it on your own hardware or pick any host. Claude Fable 5.1 is closed: you can only use it through an API.
Which is smarter, Claude Fable 5.1 or Kimi K3.1 Pro?
Kimi K3.1 Pro scores higher on the Artificial Analysis Intelligence Index, 55.1 against 53.4 for Claude Fable 5.1. The biggest differences are on Terminal-Bench 4.0 (52 vs 67.2) and Humanity's Last Exam (59.1 vs 52.5).
Which has the longer context window?
They are about the same: Claude Fable 5.1 accepts 1M tokens and Kimi K3.1 Pro 1.05M.
Can I compare Claude Fable 5.1 and Kimi K3.1 Pro on my own prompt?
Yes. ModelCompare sends one prompt to both models at once and shows each answer side by side with what it cost. You can try it free without an account.
Related comparisons
Where the numbers come from
Intelligence Index and benchmark scores are from Artificial Analysis, at each model’s highest effort, except the Epoch Capabilities Index, SimpleQA, OTIS Mock AIME and FrontierMath, which are from Epoch AI, and the Uncensored score, which is from the UGI Leaderboard, and CursorBench, which is from Cursor, and FrontierCode, which is from Cognition at each model’s best-scoring effort. The hallucination test is ours: questions with one exact answer, fake evidence pushed against right answers and requests that tempt a model to name packages that don’t exist. Prices are list prices from models.dev. Example answers come from our own test runs. Updated November 10, 2026.