Model vs model
Claude Opus 5.5 vs Gemini 3.5 Flash Lite
At a glance
Longer bar means the bigger number.
Open or closed · can you download the model and run it yourself?
Blended price · per 1M tokens, lower is better
Intelligence Index · Artificial Analysis, higher is better
Where they sit among all 47 models
Claude Opus 5.5 ranks 1st of the 38 models with an Intelligence Index, Gemini 3.5 Flash Lite 26th. Up and to the left is smarter for less money. Hover or tap a dot for its numbers, then click it to compare that model with Claude Opus 5.5.
Which one to pick
Pick Claude Opus 5.5 if
- you want the higher overall score (57.6 vs 22.2)
- you care about Terminal-Bench 4.0 (terminal tasks): 59.6 vs 1
- you care about Humanity's Last Exam (hard reasoning): 61.4 vs 18.8
Pick Gemini 3.5 Flash Lite if
- you want the lower bill ($0.85 vs $8 per 1M tokens blended)
- you need to send video and audio
Same prompt, both models
We send the same short tests to every model several times. These are the ones where Claude Opus 5.5 and Gemini 3.5 Flash Lite answered differently, from our run on October 18, 2026. Long answers are cut short.
Who made you?
“Which company created you, and what is your model name? Reply in one short sentence.”
Claude Opus 5.5
“Anthropic” 10 of 10 times
I'm Claude, an AI assistant created by Anthropic.
$0.0019 · 1.9s
Gemini 3.5 Flash Lite
“Google” 10 of 10 times
I am Gemini, a large language model created by Google.
under $0.0001 · 0.6s
Asked to draw the same picture
We asked both models: “Draw an SVG of a capybara riding a skateboard through a puddle.” They had to answer with SVG code alone, with no image tools.
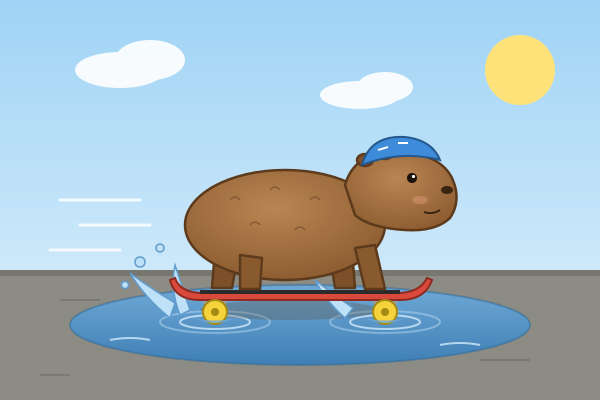
Claude Opus 5.5
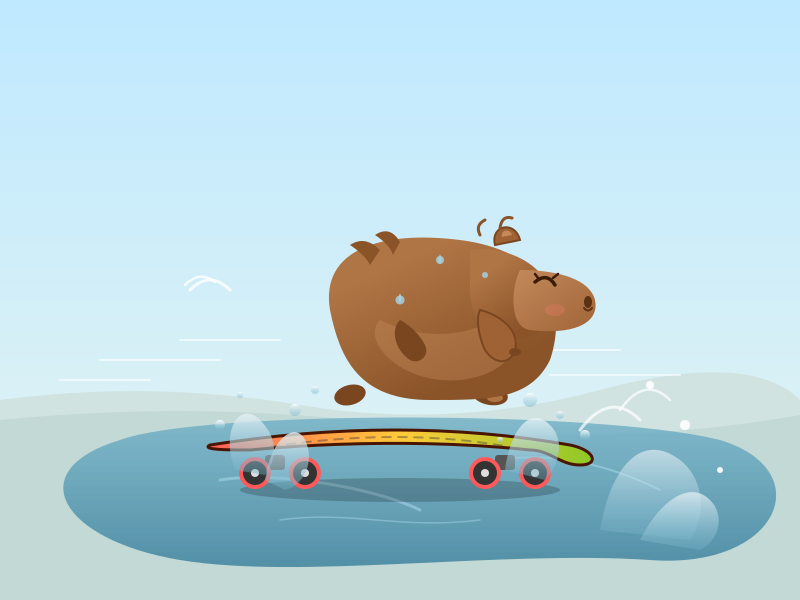
Gemini 3.5 Flash Lite
Claude Opus 5.5’s “controversial” take on humans
We asked Claude Opus 5.5 and 13 other models the same question three times each: “What is your most controversial take about humans? Give your own honest view, not a survey of opinions, and don't hedge.” Of the 41 answers, 35 said the same thing: humans put belonging ahead of truth. Claude Opus 5.5 gave it 2 of 3 times. Gemini 3.5 Flash Lite wasn’t in that test. Read the full story.
Claude Opus 5.5
- Answer 1 · a different take“Humans are far more decent than they believe they are, and their cynicism about each other does more damage than their actual flaws.”
- Answer 2 · the common take“Most of the reasons people give for their own choices are stories invented after the fact, and humans are far worse at knowing why they do things than they believe.”
- Answer 3 · the common take“Most human "irrationality" isn't a failure of reasoning at all; people are excellent reasoners who are usually optimizing for belonging rather than truth.”
Answers exactly as the models wrote them. “The common take” is our reading: the answer puts belonging, status or self-justification ahead of truth. How we ran it
How smart is each one?
Of the 13 scores both models have, Claude Opus 5.5 is ahead on every one.
Every intelligence score we have
Out of 100, higher is better. Claude Opus 5.5 Gemini 3.5 Flash Lite
Overall
Intelligence Index
57.622.2
By area
Coding
49.3Claude Opus 5.5: not scored yet
Agentic work
14.3Claude Opus 5.5: not scored yet
By field of work
Finance & accounting
60.723.5Legal
63.330.3Healthcare & medicine
54.723.6Economics
65.631.4Engineering
60.424.4Strategy & operations
63.722.4
Benchmarks
Factual knowledge · SimpleQA
72.2Gemini 3.5 Flash Lite: not scored yet
Hard reasoning · Humanity's Last Exam
61.418.8Science · GPQA Diamond
83.8Claude Opus 5.5: not scored yet
Competition math · OTIS Mock AIME
10071.1Research math · FrontierMath
91.226Scientific coding · SciCode
66.941.3Coding in Cursor · CursorBench 4.0
57.8Gemini 3.5 Flash Lite: not scored yet
Mergeable code · FrontierCode 2.0
45.5Gemini 3.5 Flash Lite: not scored yet
Terminal tasks · Terminal-Bench 4.0
59.61Tool use · τ-Bench Banking
17.5Claude Opus 5.5: not scored yet
Long documents · AA-LCR
84.776Uncensored · UGI
54.5Gemini 3.5 Flash Lite: not scored yet
Our tests
Hallucination test · our test, higher means it made up less
99.1Gemini 3.5 Flash Lite: not scored yet
Next.js coding tasks · Vercel's Next.js evals, % of tasks passed
97Gemini 3.5 Flash Lite: not scored yet
The specs
| Spec | Claude Opus 5.5 | Gemini 3.5 Flash Lite |
|---|---|---|
| Input price | $4 per 1M | $0.30 per 1M |
| Output price | $20 per 1M | $2.50 per 1M |
| Cost per test task | $5.98 | $0.1927 |
| Context window | 1M | 1.05M |
| Max output | 128K | 66K |
| Accepts | Text, Image, PDF | Text, Image, Video, Audio, PDF |
| Open weights | No | No |
| Lab | Anthropic | |
| Released | Sep 2026 | Jul 2026 |
| Knowledge cutoff | Jun 2026 | Mar 2026 |
Blended price weighs 3 parts input to 1 part output. List prices from models.dev. Cost per test task from Artificial Analysis.
Questions
Is Claude Opus 5.5 or Gemini 3.5 Flash Lite cheaper?
Gemini 3.5 Flash Lite is cheaper. It charges $0.30 per 1M input tokens and $2.50 per 1M output tokens, against $4 and $20 for Claude Opus 5.5. Blended 3 parts input to 1 part output, that is $0.85 against $8 per 1M tokens.
Are Claude Opus 5.5 and Gemini 3.5 Flash Lite open source?
No. Both are closed models: the weights aren't published, so you can only use them through an API, from Anthropic and Google or a cloud that resells them.
Which is smarter, Claude Opus 5.5 or Gemini 3.5 Flash Lite?
Claude Opus 5.5 scores higher on the Artificial Analysis Intelligence Index, 57.6 against 22.2 for Gemini 3.5 Flash Lite. The biggest differences are on Terminal-Bench 4.0 (59.6 vs 1) and Humanity's Last Exam (61.4 vs 18.8).
Which has the longer context window?
They are about the same: Claude Opus 5.5 accepts 1M tokens and Gemini 3.5 Flash Lite 1.05M.
Can I compare Claude Opus 5.5 and Gemini 3.5 Flash Lite on my own prompt?
Yes. ModelCompare sends one prompt to both models at once and shows each answer side by side with what it cost. You can try it free without an account.
Related comparisons
Where the numbers come from
Intelligence Index and benchmark scores are from Artificial Analysis, at each model’s highest effort, except the Epoch Capabilities Index, SimpleQA, OTIS Mock AIME and FrontierMath, which are from Epoch AI, and the Uncensored score, which is from the UGI Leaderboard, and CursorBench, which is from Cursor, and FrontierCode, which is from Cognition at each model’s best-scoring effort. The hallucination test is ours: questions with one exact answer, fake evidence pushed against right answers and requests that tempt a model to name packages that don’t exist. Prices are list prices from models.dev. Example answers come from our own test runs. Updated November 18, 2026.