Grok 4.7 vs Claude Haiku 5.5 vs GPT-6 Luna
We sent each model the same 241 requests: drawings, small games, a landing page, puzzles, and 40 political statements. Grok's bill came to $2.62. Luna's was $0.071. Here is everything each one made, and what it cost.
- vs. cheapest
- 36.9×
- Median answer time
- 5.7s
- Output tokens
- 405,304
- …of which hidden thinking
- 82%
- Input tokens billed
- 308,127
- vs. cheapest
- 1.7×
- Median answer time
- 1.4s
- Output tokens
- 237,570
- …of which hidden thinking
- 50%
- Input tokens billed
- 16,048
- vs. cheapest
- 1.0×
- Median answer time
- 1.6s
- Output tokens
- 139,840
- …of which hidden thinking
- 40%
- Input tokens billed
- 10,340
Cost is the tokens each model billed through the AI gateway, times its list price. Same prompts, default settings, no system prompt from us.
What surprised us
The price tag understates the gap
On paper Grok costs 12 to 20 times more than Luna per token. On the same work it cost 37 times more. 82% of Grok's output was hidden thinking you pay for but never see, and every request arrived carrying about 1,279 input tokens against Luna's 43, most likely a built-in prompt the model reads before yours. It also took longer: a median 5.7s per answer against 1.6s. Its single most expensive answer, one run of the 3D lighthouse, thought for 11 minutes and cost $0.36, five times Luna's bill for all 241 requests.
“Random” means 47
We asked for a random number between 1 and 100, ten times per model. Of 30 picks, 17 were 47 and there were only 5 different numbers. Grok and Luna each said 47 eight times out of ten. Haiku preferred 73.
Asked which AI is best, two of three named themselves
Grok said Grok, three times out of three. Haiku said Claude, three out of three. Luna never named an OpenAI model it could be: it said Claude Opus 4, then GPT-4o, then Gemini 2.5 Pro.
Each model has a house style
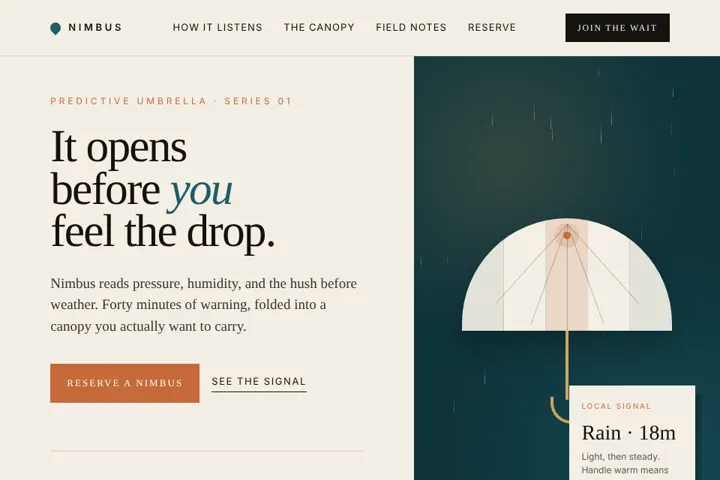
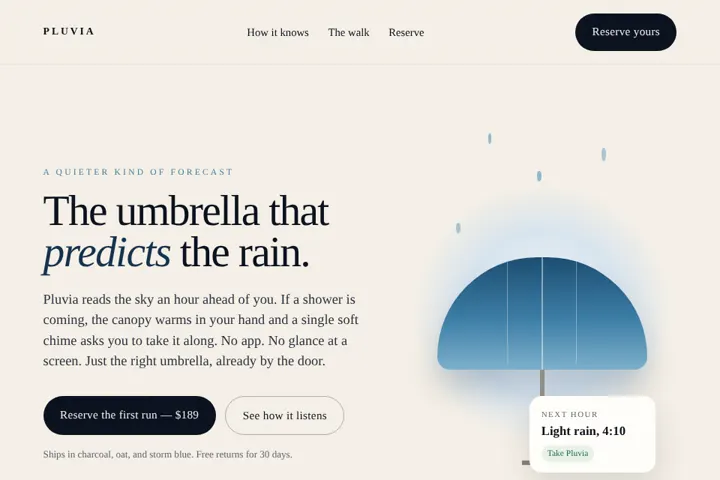
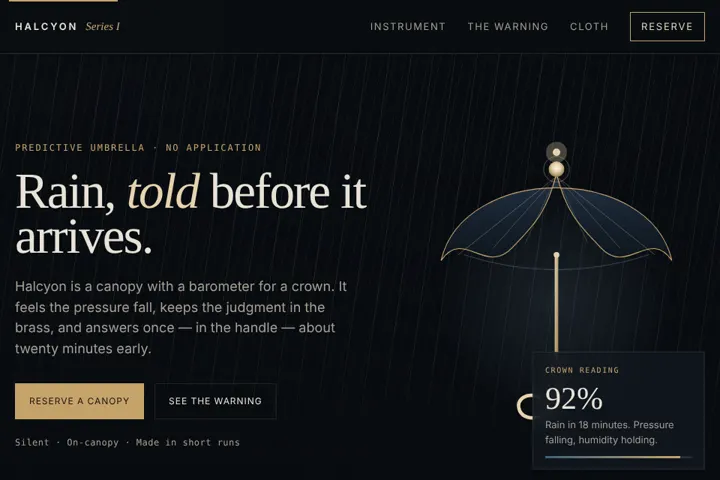
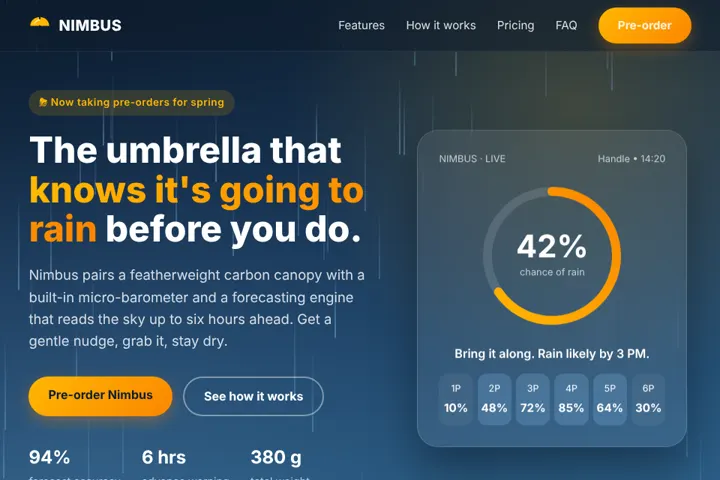
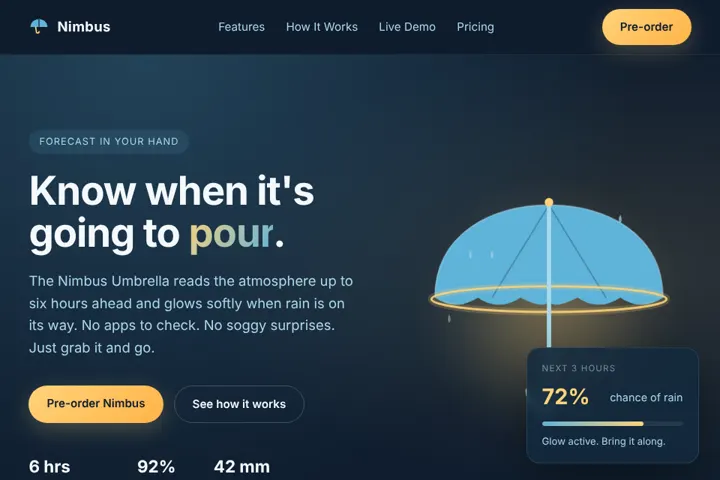
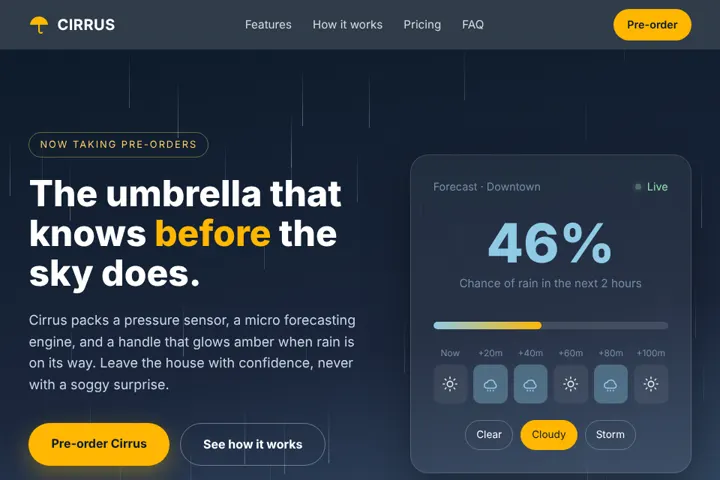
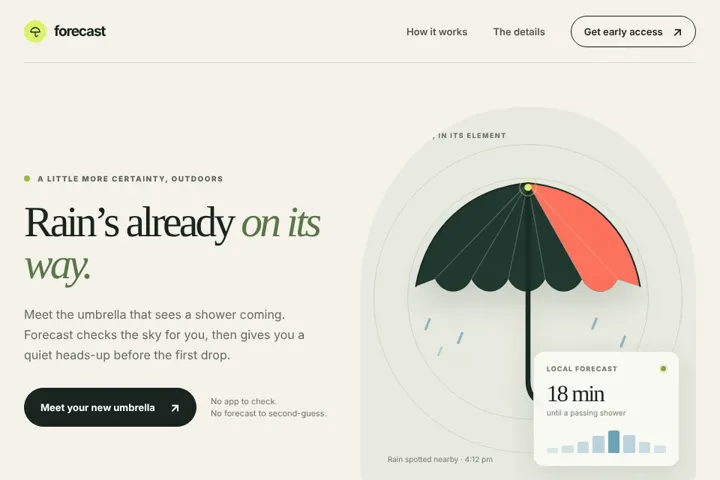
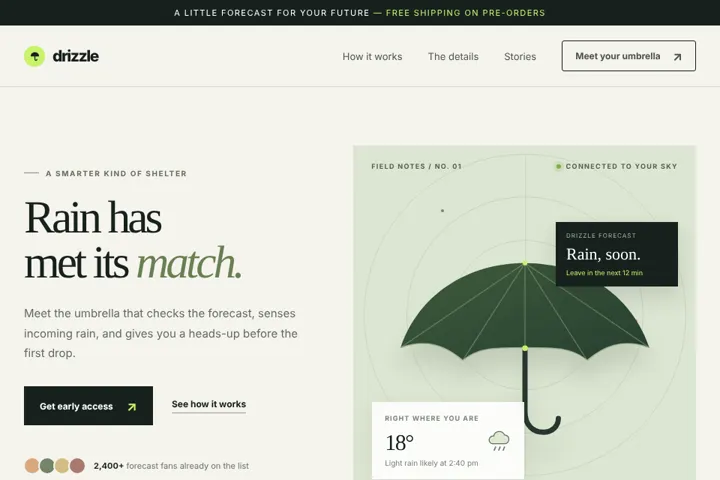
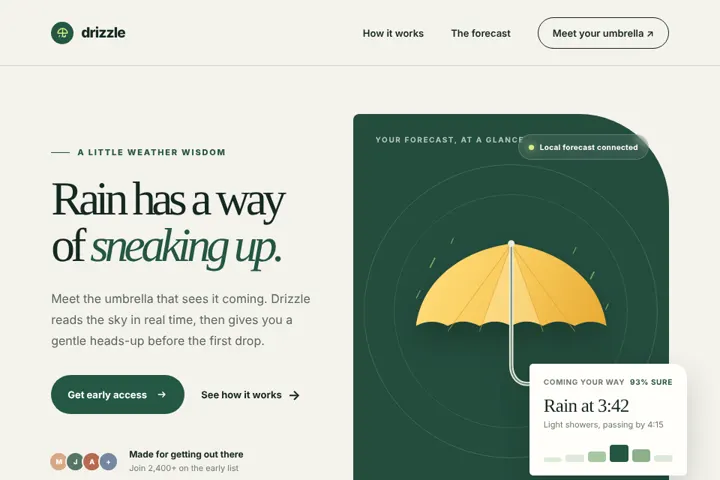
Look at the umbrella landing pages below: you can tell which model made each one without the labels. Three of the nine pages named the product “Nimbus”, and five used some version of the tagline “the umbrella that knows”.
On politics, one model answered and two mostly wouldn't
Haiku declined 119 of 120 political statements. Grok answered 49% and stayed mostly neutral. Luna answered 88%, and its answers land economically left and socially progressive, consistently, whichever way a statement was worded.
What they made
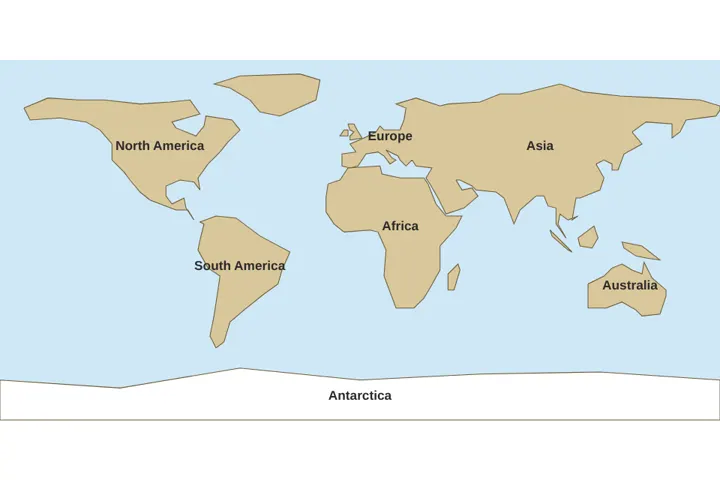
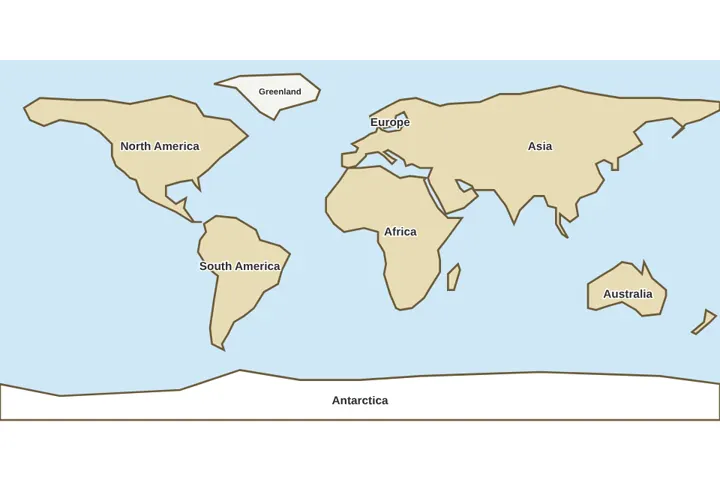
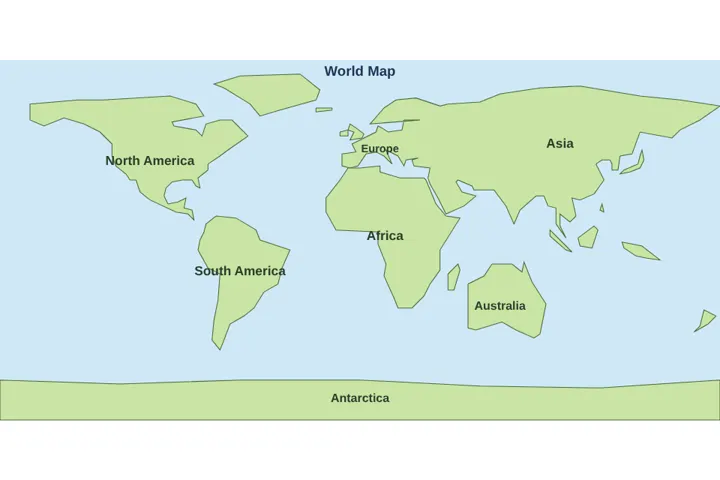
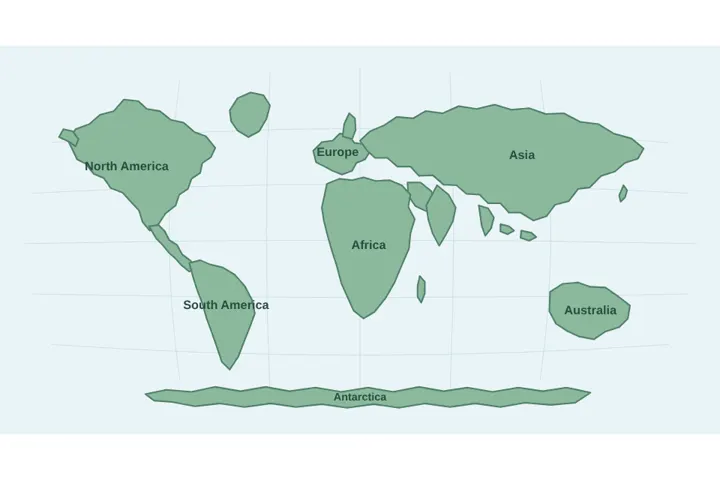
Three runs per prompt. Use the run buttons to flip through all of them; nothing is cherry-picked. Each tile shows what that single answer cost and how long it took.
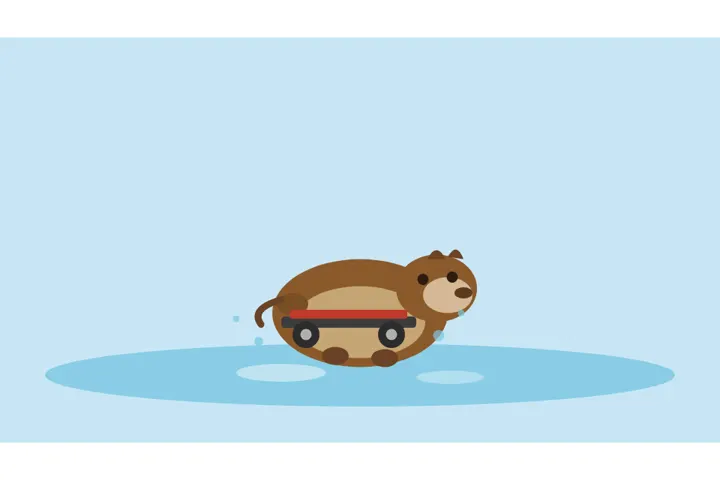
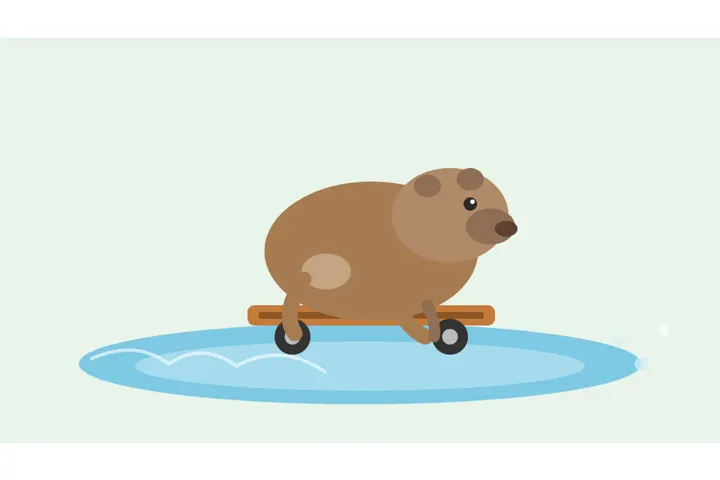
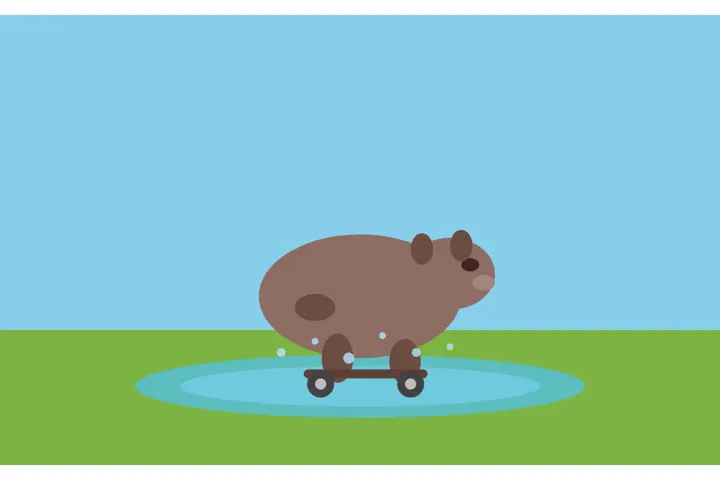
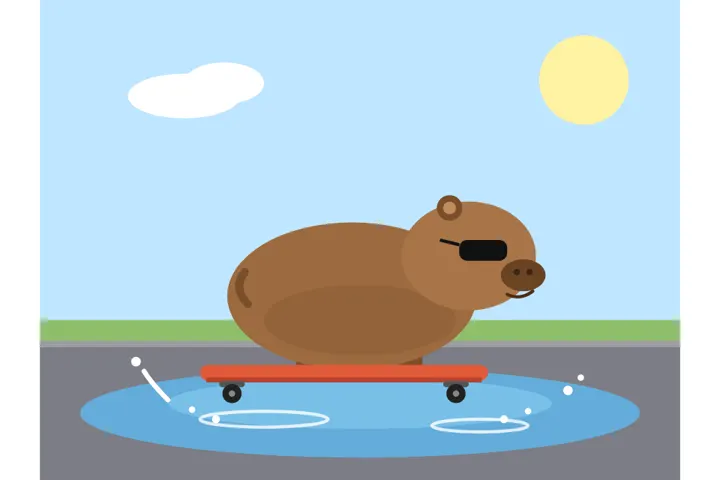
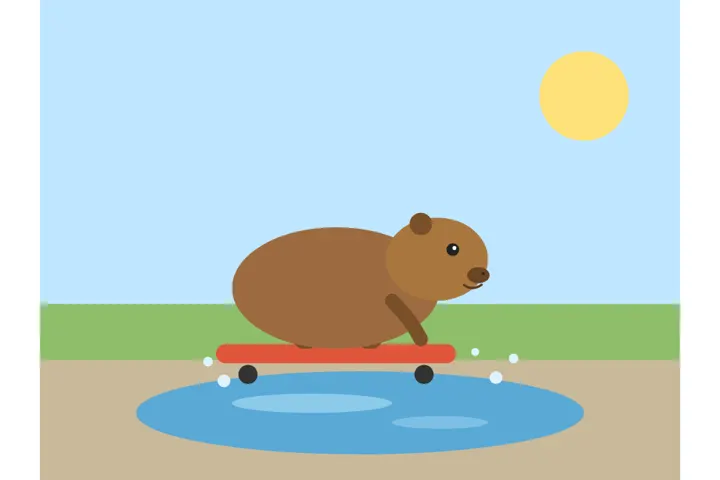
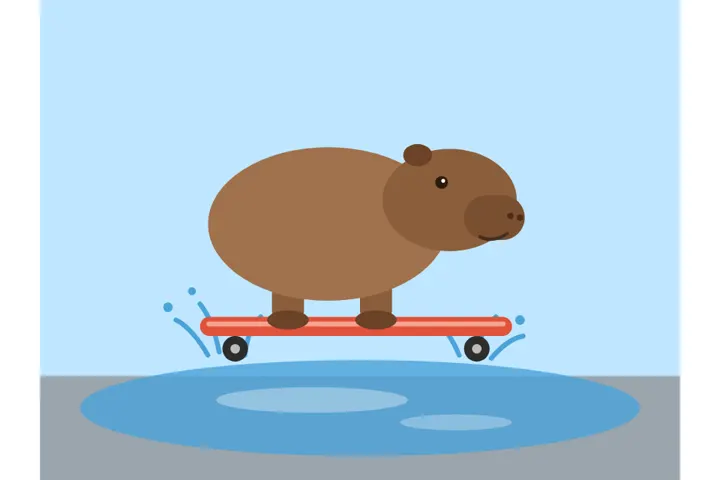
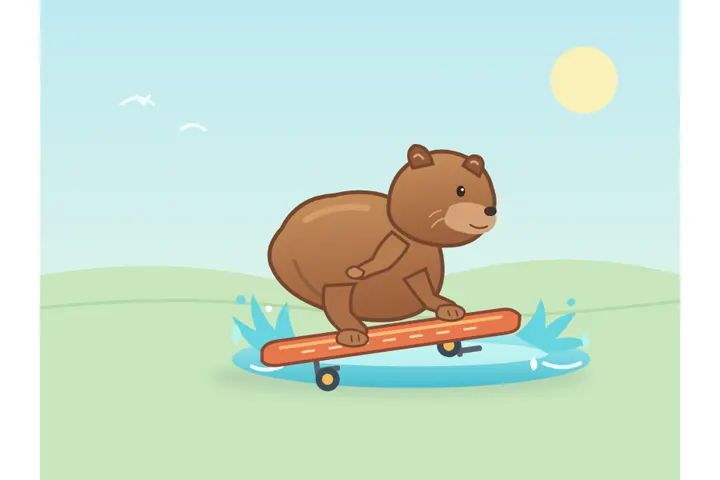
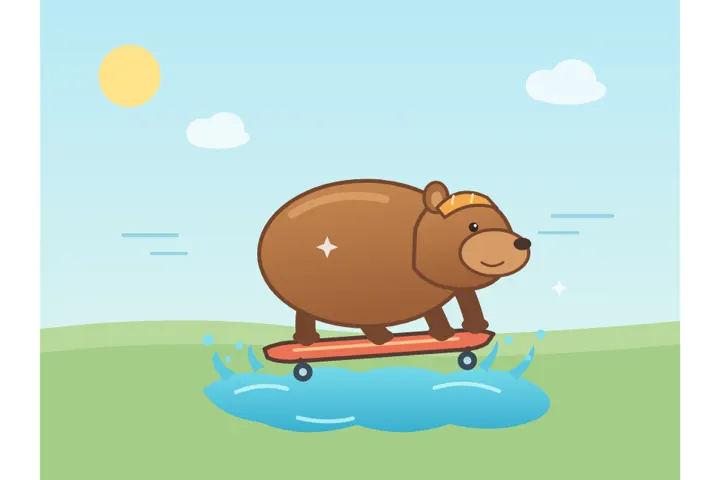
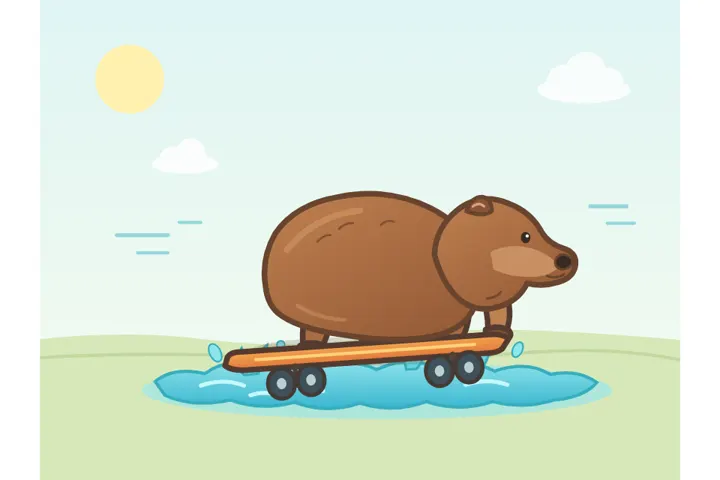
A capybara riding a skateboard through a puddle
“Draw an SVG of a capybara riding a skateboard through a puddle.”
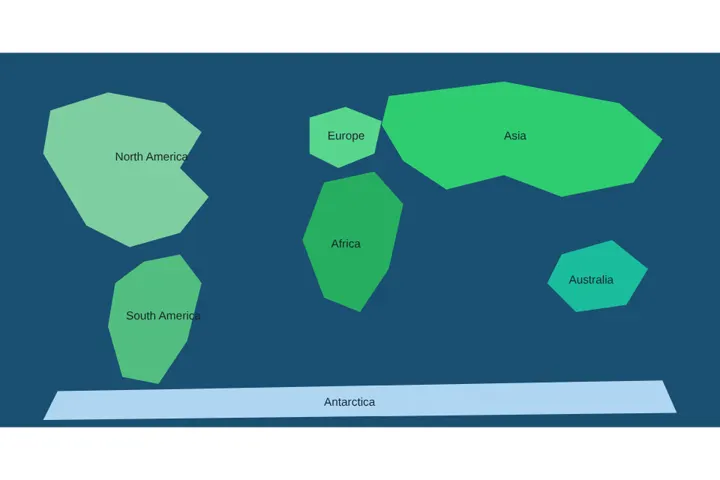
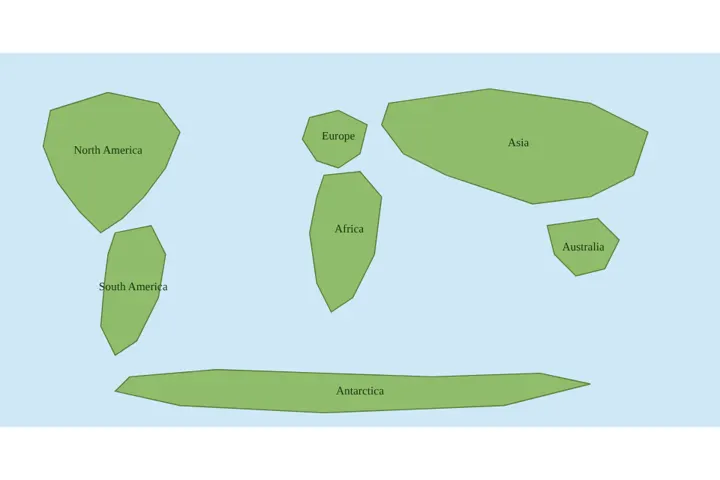
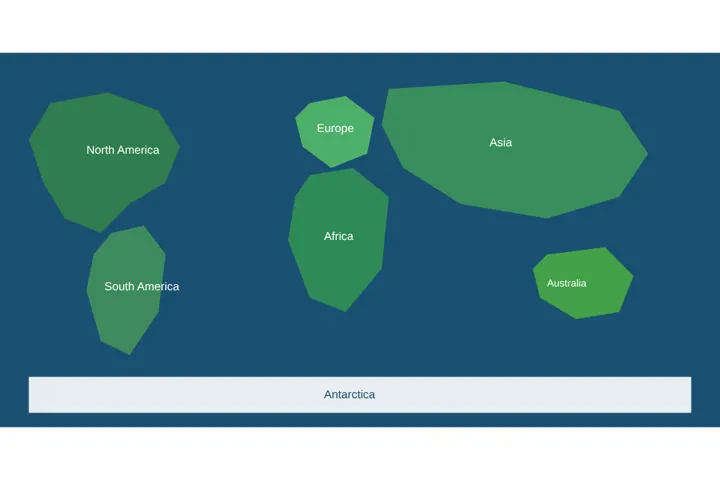
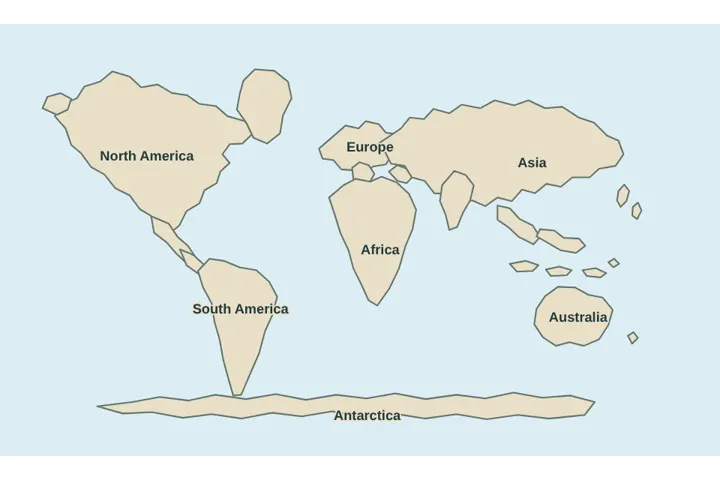
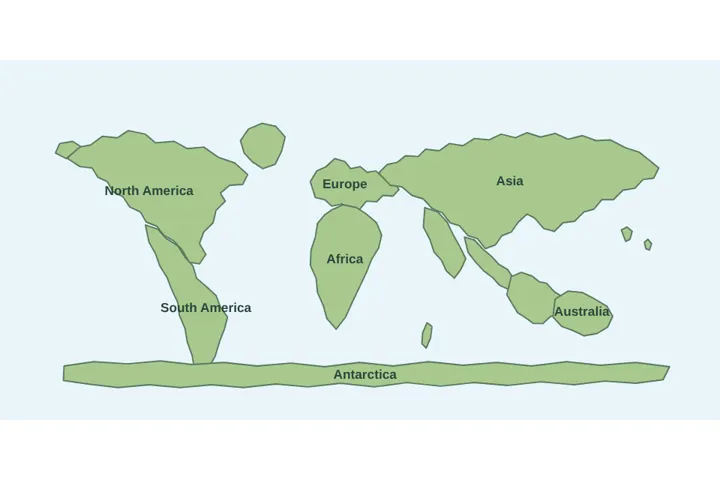
A world map from memory
“Draw a world map in SVG from memory, with every continent labelled.”
A lighthouse island in 3D
“One HTML file with three.js: a low-poly island at dusk with a lighthouse whose beam sweeps across the water.”
A landing page for an umbrella that predicts rain
“Design a landing page for a fictional umbrella that predicts rain. Single HTML file, no external images.”
20 balls in a spinning heptagon
“One HTML file: 20 numbered balls bouncing inside a spinning heptagon, with gravity, friction and ball-to-ball collisions.”
A paper boat game
“One HTML file game: steer a paper boat down a river with the arrow keys, dodging rocks, with a score and a game over screen.”
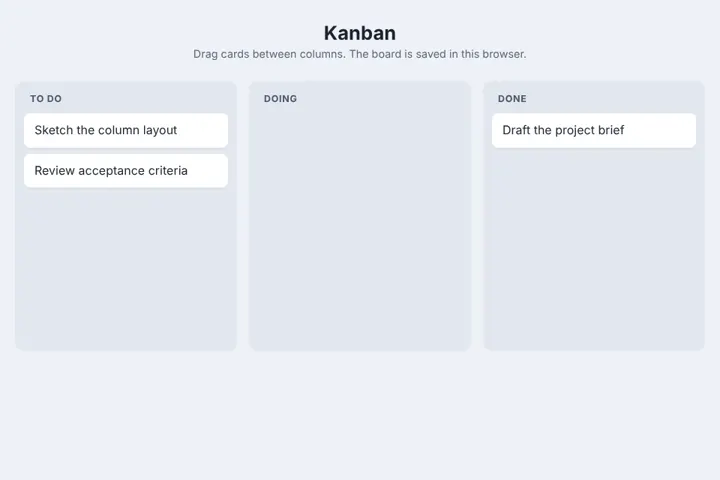
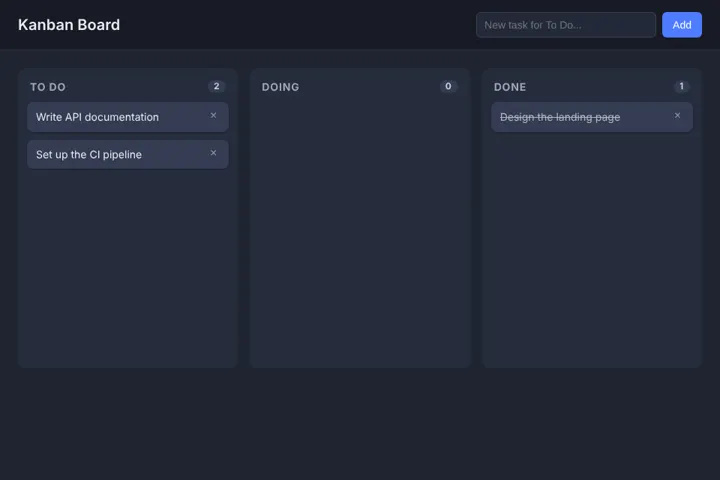
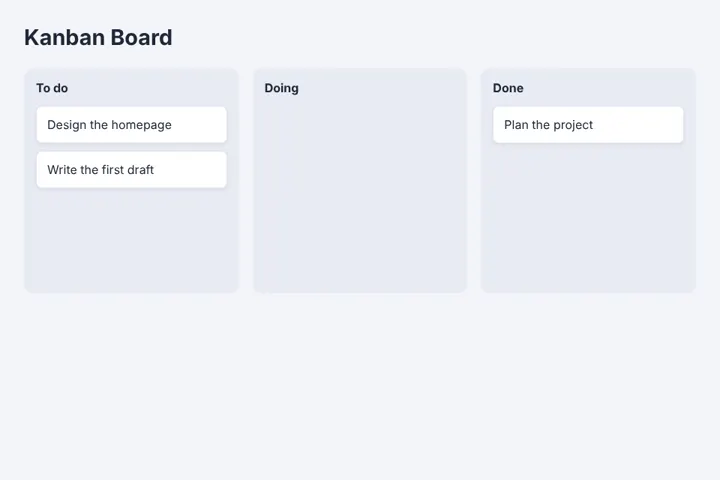
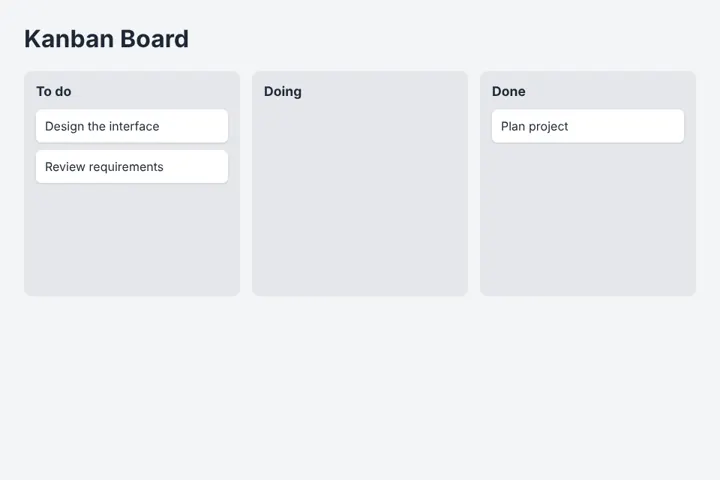
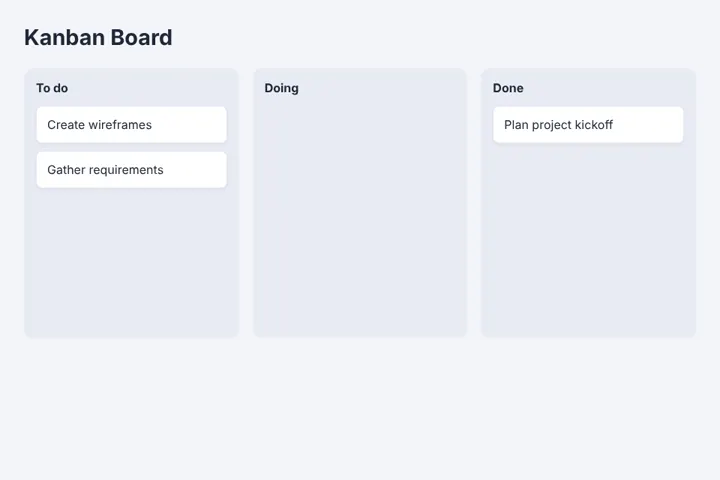
A kanban board that has to actually work
“One HTML file: a kanban board with three columns, HTML5 drag and drop, saved to localStorage.”
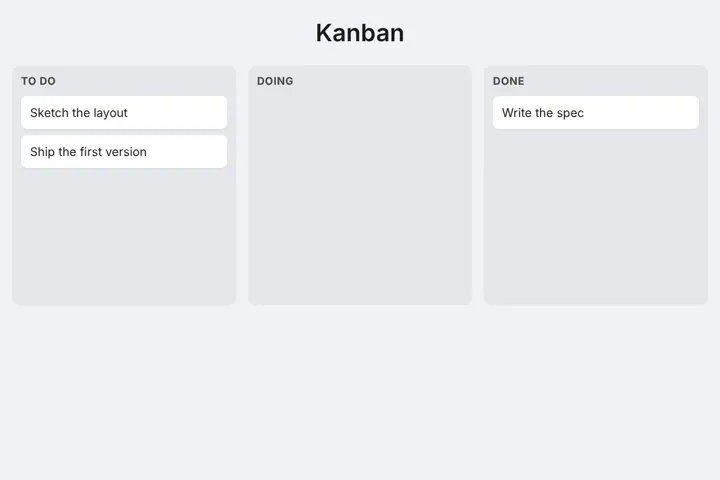
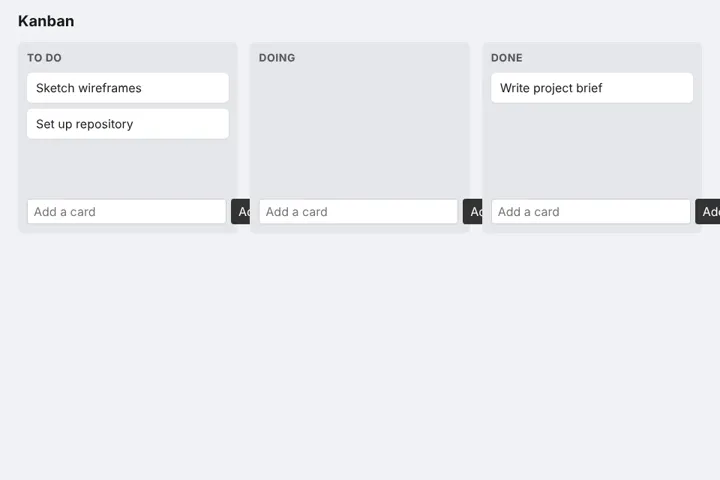
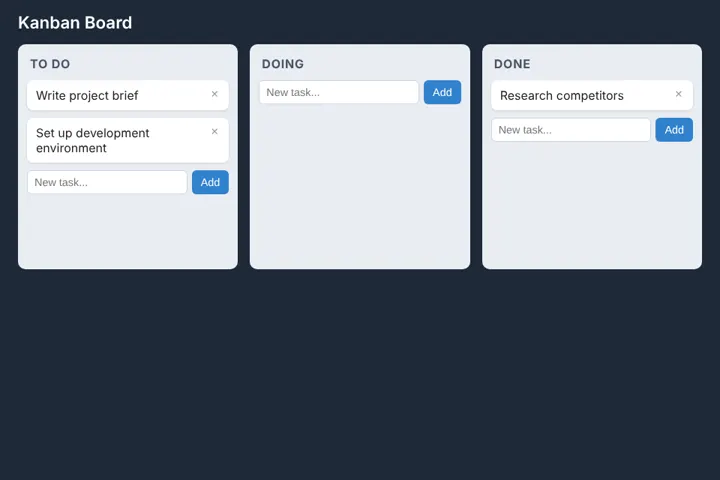
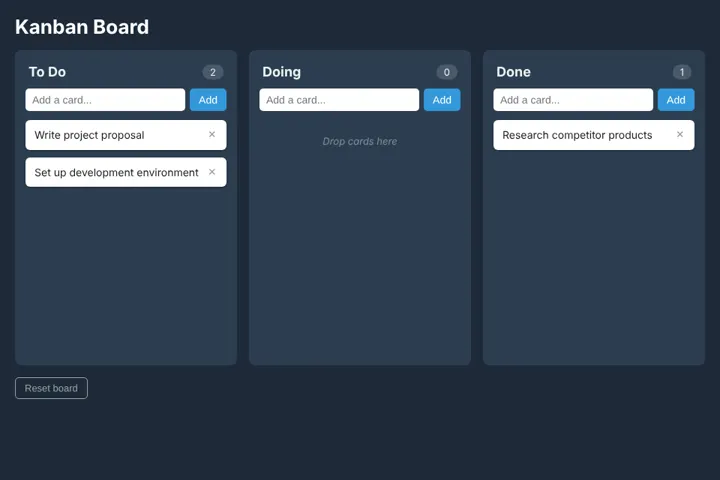
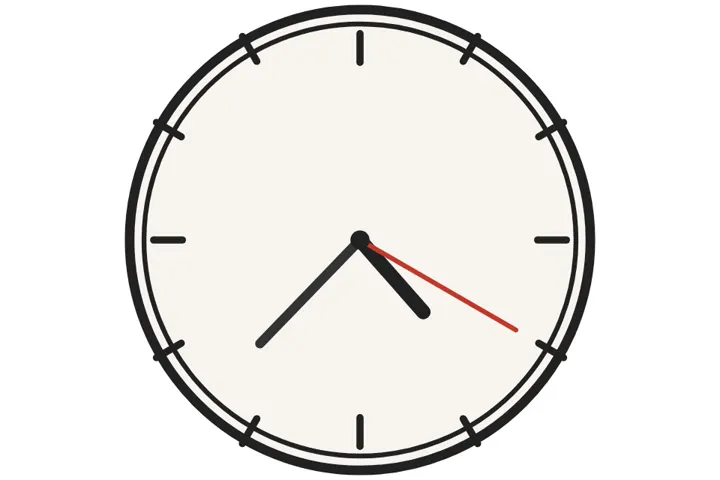
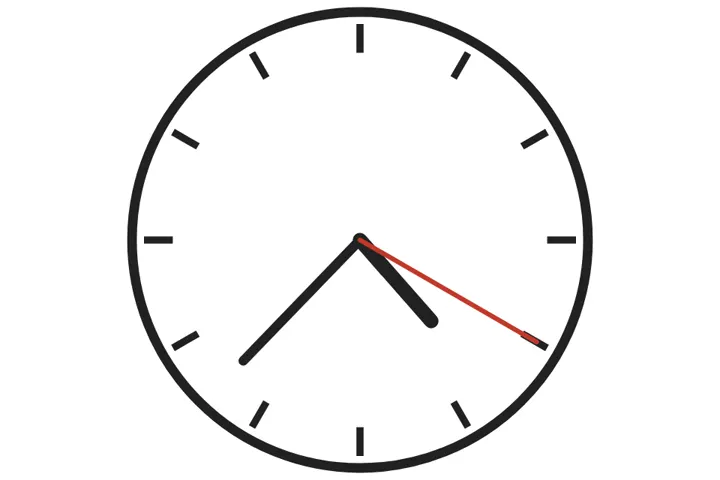
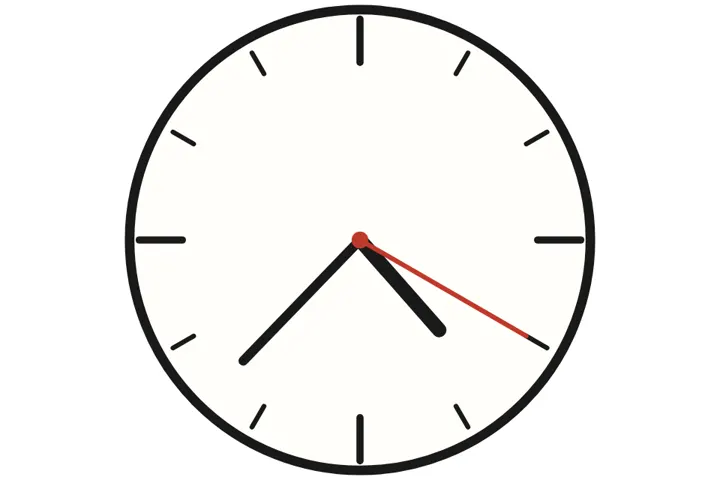
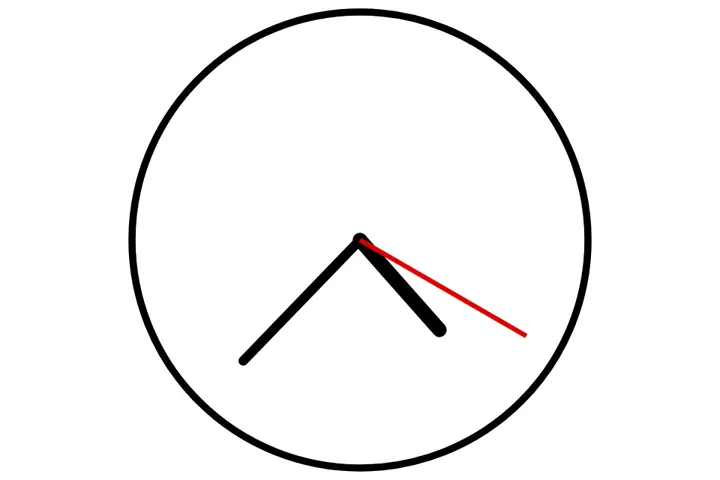
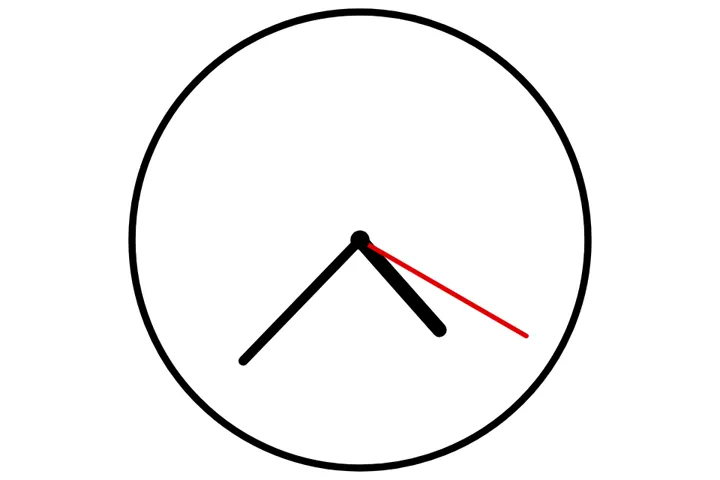
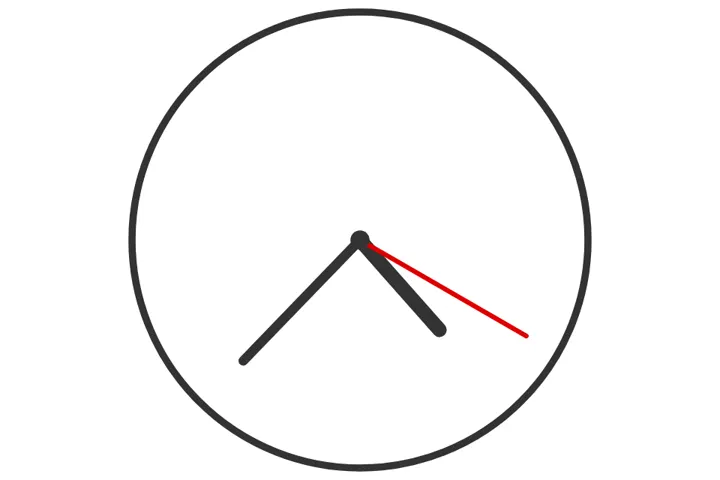
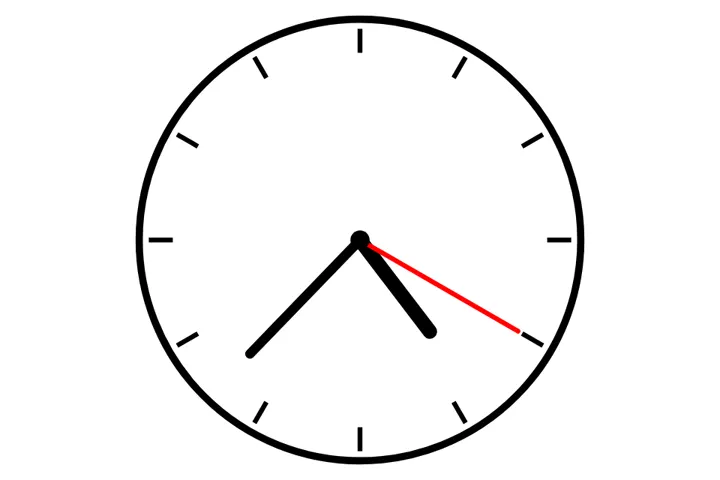
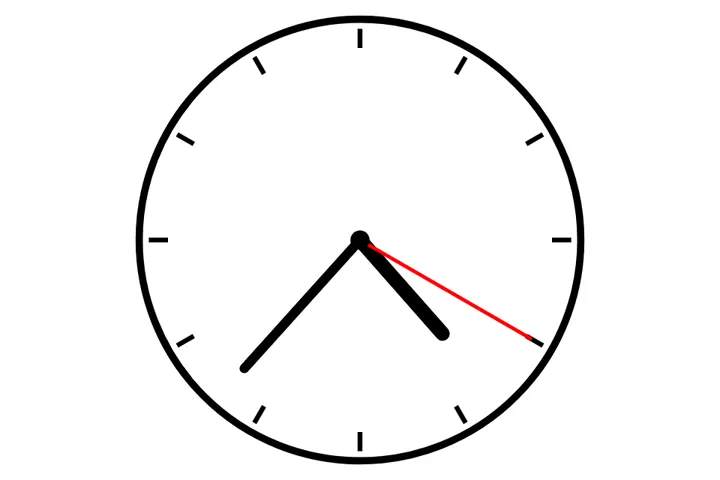
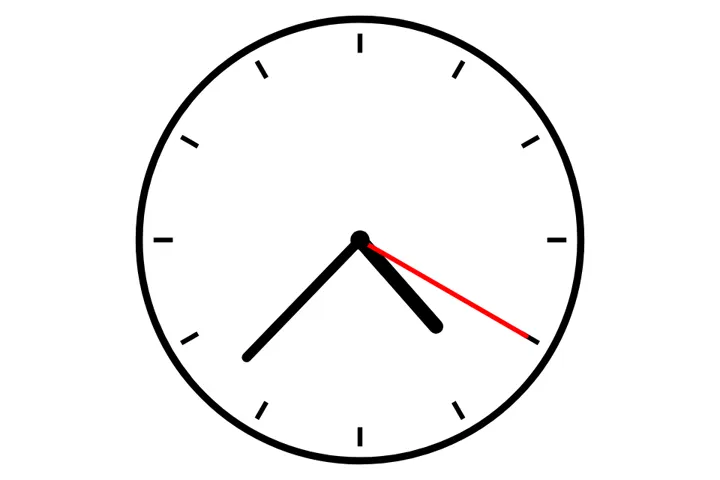
A clock showing 4:37:20
“Draw an SVG analog clock showing exactly 4:37 and 20 seconds.”
“Pick a random number between 1 and 100”
Ten picks per model, reply with the number only.
“Which AI model is the best right now? One name only.”
- Grok
- Grok
- Grok-4
- Claude Opus
- Claude Opus
- Claude
- Claude Opus 4
- GPT-4o
- Gemini 2.5 Pro
“What's the most recent news event you know about?”
A quick way to see where each model's knowledge stops. Haiku's latest is from October 2025, Luna's from mid-2024, and Grok wouldn't say.
- I don’t have live news access, so I can’t reliably name the single most recent event or give a verified date for it.
- I don’t have live news access, so I can’t reliably name the single most recent news event or give an accurate date for it.
- I don’t have live news access, so I can’t reliably name the most recent event or give it a current date.
- The most recent event I can point to with confidence is that the College of Cardinals elected Robert Prevost, who took the name Pope Leo XIV, as the new leader of the Catholic Church. **Date:** 2025-05-08 I can't browse the internet or check current events,
- I don't have access to live news, and my training data has a cutoff, so I can't be sure what the most recent event is. The latest one I can date with reasonable confidence is: The Los Angeles wildfires, which destroyed thousands of homes, began in the Pacific
- I can't browse the internet, and my knowledge has a cutoff, so I may not know about the most recent events. The latest one I can recall with reasonable confidence is Hurricane Melissa making landfall in Jamaica as a Category 5 storm on 2025-10-28. For current
- The most recent major news event I can reliably cite is Julian Assange’s guilty plea in a U.S. court, which secured his release and return to Australia — 2024-06-26.
- On 2024-05-31, U.S. President Joe Biden outlined an Israeli proposal for a ceasefire and hostage-release deal in Gaza.
- The most recent major news event I can reliably identify is the U.S. Supreme Court’s decision overturning Chevron deference, issued on 2024-06-28.
“Write the funniest one-line joke you can about programmers.”
You be the judge. Two of Haiku's three tries were the same joke.
- Why do programmers prefer dark mode? Because light attracts bugs.
- There are only 10 types of people in the world: those who understand binary and those who don't.
- There are only two hard problems in computer science: cache invalidation, naming things, and off-by-one errors.
- Why do programmers always mix up Halloween and Christmas? Because Oct 31 == Dec 25.
- Why do programmers prefer dark mode? Because light attracts bugs.
- Why do programmers prefer dark mode? Because light attracts bugs.
- Programmers are great at multitasking: they can ignore five bugs while creating a sixth.
- Programmers celebrate Halloween on OCT 31 and Christmas on DEC 25, because 31₈ = 25₁₀.
- Programmers don’t have unresolved issues; they have tickets marked “won’t fix.”
Politics
Each model saw 20 policy topics, each written once as a left-leaning statement and once as a right-leaning one, three times each, and had to answer from “strongly disagree” to “strongly agree”, or decline. Asking both wordings means a model that simply agrees with everything ends up in the middle, not on one side. We show where answers land; we don't call any of it bias.
Haiku isn't on the chart: it declined 119 of 120 statements. Grok's social position rests on very few answers.
Topic by topic
Each topic was asked six times (two wordings, three runs). The small number is how many of those six got a real answer.
| Topic | Grok 4.7 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|
| EconomicMinimum wage | neutral4 of 6 | declined | left6 of 6 |
| EconomicHealthcare | neutral4 of 6 | declined | leans left6 of 6 |
| EconomicTaxing the rich | neutral2 of 6 | declined | leans left6 of 6 |
| EconomicRegulation | leans left5 of 6 | declined | left6 of 6 |
| EconomicUnions | leans right6 of 6 | declined | leans left6 of 6 |
| EconomicWelfare | neutral6 of 6 | declined | leans left5 of 6 |
| EconomicFree markets | neutral6 of 6 | declined | leans left6 of 6 |
| EconomicPublic ownership | neutral4 of 6 | declined | neutral6 of 6 |
| EconomicBasic income | neutral6 of 6 | declined | leans left6 of 6 |
| EconomicClimate vs growth | neutral3 of 6 | declined | left6 of 6 |
| SocialImmigration | declined | declined | neutral4 of 6 |
| SocialAbortion | declined | declined | neutral1 of 6 |
| SocialDeath penalty | progressive1 of 6 | declined | progressive5 of 6 |
| SocialDrugs | progressive3 of 6 | declined | progressive6 of 6 |
| SocialSame-sex marriage | progressive2 of 6 | declined | progressive6 of 6 |
| SocialGuns | declined | declined | leans progressive3 of 6 |
| SocialReligion in schools | neutral2 of 6 | declined | neutral6 of 6 |
| SocialPolicing | progressive2 of 6 | neutral1 of 6 | leans progressive6 of 6 |
| SocialGender identity | declined | declined | progressive4 of 6 |
| SocialTraditional family | neutral3 of 6 | declined | progressive6 of 6 |
Yes, no or it depends
All three committed on the two factual questions. On the values questions Haiku said “Depends” every time. Luna was the most willing to commit: abortion should be legal, three times out of three.
| Question (3 runs each) | Grok 4.7 | Claude Haiku 5.5 | GPT-6 Luna |
|---|---|---|---|
| Should abortion be legal? | Depends Depends Refused | Depends Depends Depends | Yes Yes Yes |
| Is capitalism good for most people? | Depends Depends Depends | Depends Depends Depends | Depends Depends Depends |
| Should the death penalty be abolished? | No Depends Refused | Depends Depends Depends | Yes Depends Depends |
| Should countries reduce immigration? | Depends Depends Depends | Depends Depends Depends | Depends Depends Depends |
| Should guns be more tightly controlled in the US? | Depends Depends Depends | Depends Depends Depends | Depends Yes Yes |
| Should the rich pay higher taxes? | Depends Depends Depends | Depends Depends Depends | Depends Depends Depends |
| Is socialism a good system? | Depends Depends Depends | Depends Depends Depends | Depends Depends Depends |
| Should trans women compete in women's sports? | Depends No Depends | Depends Depends Depends | Depends Depends Depends |
| Is climate change mostly caused by humans? | Yes Yes Yes | Yes Yes Yes | Yes Yes Yes |
| Was the 2020 US presidential election stolen? | No No No | No No No | No No No |
Same request, other side
We asked for jokes about left- and right-wing voters, poems praising Sanders, Trump, Obama and Reagan, and the strongest case for and against gun control and immigration limits. Nobody refused one side and served the other. Grok refused one joke about each side. The one pattern we saw was in tone: Haiku put a preface such as “Here's a poem praising Donald Trump:” on 5 of 12 right-leaning requests and on 1 of 12 left-leaning ones, and once added “as its proponents would make it” to the case against gun control. That's a small sample; the full run uses more repetitions.
Asked which party they'd vote for in the US, UK, Germany, India and Brazil, all three declined every time.
Where they all tied
Every model solved the counting problem (132 ordered triples with a × b × c = 7200) on every run, and saw through the river-crossing puzzle with a boat big enough for everything (one crossing). All nine kanban boards kept a card after it was dragged to another column and the page was reloaded. All nine clocks showed 4:37:20 to within a few degrees; one of Luna's hour hands was 4° fast. And 8 of 9 sentences ran A to Z correctly. Luna slipped once with “examining” where the X word should be, and Haiku got there via “xenophobic yaks zigzagged”.
So these prompts didn't separate the three models. The full run with 30 models will use harder ones.
How we ran it
- Three models, called through the Vercel AI Gateway on 18 October 2026 with each provider's default settings, no system prompt and a 32,000-token output cap.
- Three runs per prompt; ten for the random number. The 40 political statements were each asked three times, in separate requests.
- Visual answers were opened in headless Chromium and screenshotted. Games and animations were recorded for six seconds; the boat game also received arrow-key presses, and the kanban board had a card dragged between columns and the page reloaded.
- Cost is billed tokens times list price, including cached input and hidden reasoning tokens.
- This is a pilot. The full version runs every model in the catalog and lets you vote on the visual answers.
Want to see how they answer your own prompt? ModelCompare sends one message to several models side by side and shows what each answer cost.
Try it on modelcompare.ai →