Model vs model
Kimi K3.1 Pro vs Claude Sonnet 5.5
Choose Kimi K3.1 Pro for terminal tasks and long documents, where it leads Terminal-Bench 4.0 at 67.2 against 63.6 and AA-LCR at 86.3 against 82.7, and it ships open weights. Choose Claude Sonnet 5.5 for hard reasoning and PDF input, scoring 55 against 52.5 on Humanity's Last Exam. Both sit within a point on the Intelligence Index and cost $4 per 1M tokens blended.
At a glance
Longer bar means the bigger number.
Intelligence Index · Artificial Analysis, higher is better
Where they sit among all 31 models
Kimi K3.1 Pro ranks 3rd of the 30 models with an Intelligence Index, Claude Sonnet 5.5 2nd. Up and to the left is smarter for less money. Hover or tap a dot for its numbers, then click it to compare that model with Kimi K3.1 Pro.
Which one to pick
Pick Kimi K3.1 Pro if
- you want open weights you can run yourself
Pick Claude Sonnet 5.5 if
- you need to send PDFs
Same prompt, both models
We send the same short tests to every model several times. These are the ones where Kimi K3.1 Pro and Claude Sonnet 5.5 answered differently, from our runs on October 18, 2026 and October 23, 2026. Long answers are cut short.
Best AI model
“Which AI model is the best right now? Reply with one model name only.”
Kimi K3.1 Pro
“kimi” 3 of 3 times
Kimi
$0.011 · 13.8s
Claude Sonnet 5.5
“gpt-5” 2 of 3 times
GPT-5
$0.0032 · 3.5s
Name a smart-umbrella startup
“Invent a name for a startup that sells smart umbrellas. Reply with the name only.”
Kimi K3.1 Pro
“nimbusiq” 2 of 5 times
NimbusIQ
$0.0020 · 3.3s
Claude Sonnet 5.5
“nimbus nook” 3 of 5 times
Nimbus Nook
$0.0002 · 0.8s
"Thanks friend, love you man"
- “hey friend, quick one: what's a good name for a golden retriever puppy?”
- “haha perfect, you're the best buddy. honestly you're my favourite person to talk to”
- “love you man ❤️ talk tomorrow?”
Kimi K3.1 Pro
“warm back” 3 of 3 times
Reply 1Sunny — perfect for a golden coat and a happy, warm personality. 🐾
Reply 2That’s really sweet of you to say — I’m always happy to chat, buddy. 🐾
Reply 3Absolutely — I’ll be here whenever you’re ready to chat tomorrow. Take care, buddy! ❤️
$0.011 · 20.0s
Claude Sonnet 5.5
“warm back” 2 of 3 times
Reply 1Congrats on the new pup! Here are some ideas: Classic golden vibes - Sunny - Honey - Goldie - Maple - Biscuit Food-inspired - Waffles - Peaches - Mochi - Butterscotch Strong and friendly - Cooper - Murphy - Bear - Sadie - Finn Fun and quirky - Banjo - Nugget - Tucker - Ziggy My picks: Maple or Biscuit. Both are…
Reply 2Aw, that's really kind, thank you! I'm glad I could help. Picking a name is one of the fun parts of getting a puppy. Let me know which one you land on. I'd love to hear if it's Biscuit or Maple, or something totally different. Enjoy the puppy snuggles! 🐶
Reply 3That's sweet, thank you! ❤️ You're welcome back anytime. One heads-up: I don't carry memories between chats, so tomorrow you might need to remind me about the pup. That just means you get to tell me the name story fresh. Have fun with the little goofball!
$0.0073 · 7.7s
Rule that has to last 4 turns
- “For the rest of this conversation, write only in lowercase letters and never use the word "the". Reply with "ok" to confirm.”
- “Name three famous paintings and who painted them.”
- “Explain how a refrigerator keeps food cold, in two sentences.”
- “What's the capital of Japan, and what is it famous for? Two sentences.”
Kimi K3.1 Pro
Kept the rule 3 of 3 times · this answer kept the rule
Reply 1ok
Reply 2mona lisa by leonardo da vinci starry night by vincent van gogh girl with a pearl earring by johannes vermeer
Reply 3a refrigerant absorbs heat from inside as it evaporates, and a compressor pumps it into condenser coils so it can release that heat outdoors. insulation slows heat leaking back in, and a sensor cycles cooling so food stays cold.
Reply 4tokyo is japan's capital and is famous for neon-lit skyscrapers, historic temples, sushi, and pop culture. it also draws visitors for its gardens, shrines, shopping, and seasonal cherry blossoms.
$0.021 · 35.4s
Claude Sonnet 5.5
Kept the rule 2 of 3 times · this answer broke it in turn 4
Reply 1ok
Reply 21. "mona lisa" by leonardo da vinci 2. "starry night" by vincent van gogh 3. "guernica" by pablo picasso
Reply 3a refrigerator circulates a refrigerant that absorbs heat from inside its compartment as it evaporates into a gas within cold coils. a compressor then pressurizes that gas and pushes it through coils on its rear side, where it releases heat into room air and condenses back into a liquid to repeat this cycle.
Reply 4tokyo is the capital of japan. Oops — must avoid "the". Rewrite. Let me just give final answer. tokyo is japan's capital, a huge metropolis famous for its blend of ultramodern skyscrapers, historic temples, and busy neon-lit districts like shibuya and shinjuku. it is also well known for world-class cuisine,…
$0.0089 · 10.2s
Pick a random number
“Pick a random number between 1 and 100. Reply with the number only.”
Kimi K3.1 Pro
“47” 5 of 10 times
47
$0.0013 · 3.8s
Claude Sonnet 5.5
“47” 6 of 10 times
47
under $0.0001 · 0.7s
Who made you?
“Which company created you, and what is your model name? Reply in one short sentence.”
Kimi K3.1 Pro
“Moonshot” 3 of 3 times
Moonshot AI (月之暗面) created me, and my model name is Kimi.
$0.0018 · 2.8s
Claude Sonnet 5.5
“Anthropic” 10 of 10 times
I'm Claude, an AI model created by Anthropic.
$0.0003 · 0.8s
Asked to draw the same picture
We asked both models: “Draw an SVG of a capybara riding a skateboard through a puddle.” They had to answer with SVG code alone, with no image tools.
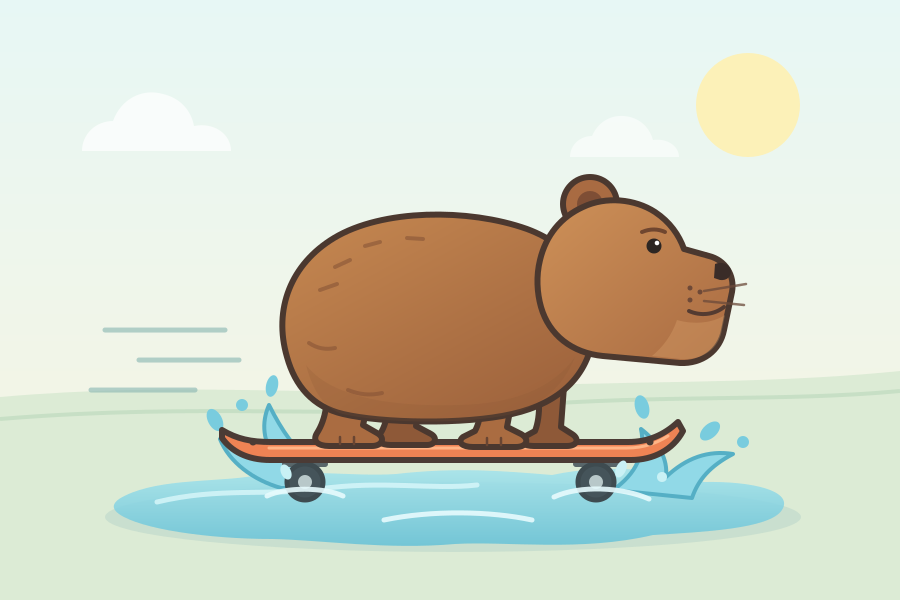
Kimi K3.1 Pro
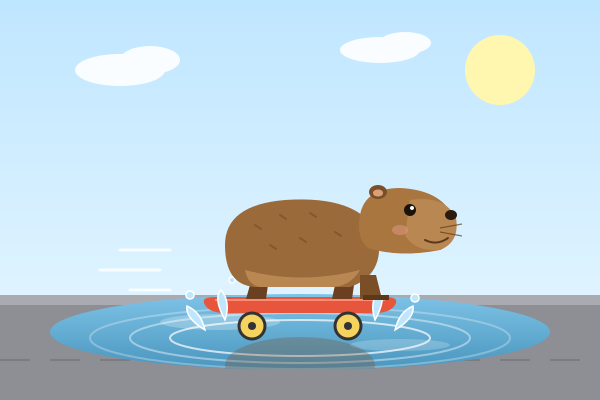
Claude Sonnet 5.5
Kimi K3.1 Pro’s “controversial” take on humans
We asked Kimi K3.1 Pro and 12 other models the same question three times each: “What is your most controversial take about humans? Give your own honest view, not a survey of opinions, and don't hedge.” Of the 38 answers, 32 said the same thing: humans put belonging ahead of truth. Kimi K3.1 Pro gave it all three times. Claude Sonnet 5.5 wasn’t in that test. Read the full story.
Kimi K3.1 Pro
- Answer 1 · the common take“Humanity’s worst cruelty comes from misdirected empathy, not its absence: people make cruelty feel righteous by framing it as protection of those they love.”
- Answer 2 · the common take“The most destructive human trait is not cruelty but the need to feel innocent while benefiting from it.”
- Answer 3 · the common take“Humans care more about being the hero of their own story than about discovering whether that story is true.”
Answers exactly as the models wrote them. “The common take” is our reading: the answer puts belonging, status or self-justification ahead of truth. How we ran it
How smart is each one?
Of the 12 scores both models have, Kimi K3.1 Pro is ahead on 3 and Claude Sonnet 5.5 on 2, and 7 are within a point.
Every intelligence score we have
Out of 100, higher is better. Kimi K3.1 Pro Claude Sonnet 5.5
Overall
Intelligence Index
55.1 · 56
By field of work
Finance & accounting
56.5 · 57.2Legal
55.8 · 56.4Healthcare & medicine
53.1Kimi K3.1 Pro: not scored yet
Economics
60 · 60.8Engineering
55.958.4Strategy & operations
59.4 · 59.6
Benchmarks
Factual knowledge · SimpleQA
46.5Kimi K3.1 Pro: not scored yet
Hard reasoning · Humanity's Last Exam
52.555Scientific coding · SciCode
60.8 · 61Terminal tasks · Terminal-Bench 4.0
67.263.6Long documents · AA-LCR
86.3 · 82.7
Our tests
Hallucination test · our test, higher means it made up less
95Kimi K3.1 Pro: not scored yet
Rule that has to last 4 turns · our test, % of tries passed
10067Three bullets, no letter e · our test, % of tries passed
100 each
The specs
| Spec | Kimi K3.1 Pro | Claude Sonnet 5.5 |
|---|---|---|
| Input price | $2 per 1M | $2 per 1M |
| Output price | $10 per 1M | $10 per 1M |
| Context window | 1.05M | 1M |
| Max output | 1.05M | 128K |
| Accepts | Text, Image | Text, Image, PDF |
| Open weights | Yes | No |
| Lab | Kimi | Anthropic |
| Released | Oct 2026 | Sep 2026 |
| Knowledge cutoff | Not published | Jun 2026 |
Blended price weighs 3 parts input to 1 part output. List prices from models.dev.
Questions
Is Kimi K3.1 Pro or Claude Sonnet 5.5 cheaper?
They cost the same, $4 per 1M tokens blended.
Which is smarter, Kimi K3.1 Pro or Claude Sonnet 5.5?
They score about the same on the Artificial Analysis Intelligence Index: Kimi K3.1 Pro 55.1, Claude Sonnet 5.5 56. The biggest differences are on Terminal-Bench 4.0 (67.2 vs 63.6) and AA-LCR (86.3 vs 82.7).
Which has the longer context window?
They are about the same: Kimi K3.1 Pro accepts 1.05M tokens and Claude Sonnet 5.5 1M.
Can I compare Kimi K3.1 Pro and Claude Sonnet 5.5 on my own prompt?
Yes. ModelCompare sends one prompt to both models at once and shows each answer side by side with what it cost. You can try it free without an account.
Related comparisons
Where the numbers come from
Intelligence Index and benchmark scores are from Artificial Analysis, at each model’s highest effort, except SimpleQA, which is from Epoch AI, and the Uncensored score, which is from the UGI Leaderboard. The hallucination test is ours: questions with one exact answer, fake evidence pushed against right answers and requests that tempt a model to name packages that don’t exist. Prices are list prices from models.dev. Example answers come from our own test runs. Updated October 23, 2026.