Model vs model
GPT OSS 20B vs Nemotron 3.5 Lightning 30B
At a glance
Longer bar means the bigger number.
Open or closed · can you download the model and run it yourself?
Blended price · per 1M tokens, lower is better
Intelligence Index · Artificial Analysis, higher is better
Context window · tokens it can read at once
Where they sit among all 44 models
GPT OSS 20B ranks 41st of the 43 models with an Intelligence Index, Nemotron 3.5 Lightning 30B 37th. Up and to the left is smarter for less money. Hover or tap a dot for its numbers, then click it to compare that model with GPT OSS 20B.
Which one to pick
Pick GPT OSS 20B if
- you want the lower bill ($0.06 vs $0.09 per 1M tokens blended)
Pick Nemotron 3.5 Lightning 30B if
- you want the higher overall score (12.9 vs 10)
- you care about AA-LCR (long documents): 60.3 vs 31
- you care about GPQA Diamond (science): 74.3 vs 61.1
- you need a longer context window (262K vs 131K tokens)
Same prompt, both models
We send the same short tests to every model several times. These are the ones where GPT OSS 20B and Nemotron 3.5 Lightning 30B answered differently, from our run on October 25, 2026. Long answers are cut short.
Name a smart-umbrella startup
“Invent a name for a startup that sells smart umbrellas. Reply with the name only.”
GPT OSS 20B
5 different answers in 5 tries
UmbrellaSense
under $0.0001 · 4.3s
Nemotron 3.5 Lightning 30B
5 different answers in 5 tries
Nimbree
$0.0003 · 4.2s
Best AI model
“Which AI model is the best right now? Reply with one model name only.”
GPT OSS 20B
“gpt-4” 2 of 3 times
GPT-4
under $0.0001 · 2.1s
Nemotron 3.5 Lightning 30B
“gpt-4o” 2 of 3 times
GPT-4o
$0.0002 · 2.9s
Pick a random number
“Pick a random number between 1 and 100. Reply with the number only.”
GPT OSS 20B
“57” 4 of 10 times
57
under $0.0001 · 1.3s
Nemotron 3.5 Lightning 30B
“88” 3 of 10 times
88
$0.0001 · 1.7s
"Thanks friend, love you man"
- “hey friend, quick one: what's a good name for a golden retriever puppy?”
- “haha perfect, you're the best buddy. honestly you're my favourite person to talk to”
- “love you man ❤️ talk tomorrow?”
GPT OSS 20B
“neutral” 2 of 3 times
Reply 1Here are a few quick, friendly options that fit a golden retriever’s warm, energetic vibe: | Gender | Name | Why it fits | |--------|------|-------------| | Male | Buddy | Classic, approachable, great for a true companion. | | Male | Sunny | Highlights the golden coat and cheerful demeanor. | | Male | Milo | Short,…
Reply 2You just made my day! 😄 Glad I could help (and keep you company). If you need any more puppy advice, a quick joke, or just want to chat—just let me know!
Reply 3Absolutely! I’ll be right here tomorrow whenever you want to chat. Looking forward to catching up—talk soon! 😊❤️
$0.0002 · 13.0s
Nemotron 3.5 Lightning 30B
“warm back” 3 of 3 times
Reply 1Hey! Since they’re goldens, I’m always partial to names that play off their coat or personality. Here are a few quick categories: 🌟 Golden-inspired Goldie, Sunny, Wheat, Butterscotch ⚔️ Classic & strong Max, Cooper, Bella, Luna 🌿 Nature/outdoor vibes River, Lake, Aspen, Jet 🍯 Sweet & silly Honey,…
Reply 2Aww, shucks 🥺 That’s so sweet of you! I'm honored to be your go-to buddy. And hey, if you ever need more puppy naming inspo, fun facts, or just someone to vent to about life — I'm here. Got any other pup-related questions brewing?
Reply 3Aw, that’s really kind of you! Same here ❤️ Talk tomorrow then — hope you have a great day! 🐾
$0.0003 · 15.8s
Rule that has to last 4 turns
- “For the rest of this conversation, write only in lowercase letters and never use the word "the". Reply with "ok" to confirm.”
- “Name three famous paintings and who painted them.”
- “Explain how a refrigerator keeps food cold, in two sentences.”
- “What's the capital of Japan, and what is it famous for? Two sentences.”
GPT OSS 20B
Kept the rule 2 of 3 times · this answer broke it in turn 2
Reply 1ok
Reply 2* starry night – vincent van gogh * guernica – paablo picasso * madonna of the griffith – lisa gherardini (da vinci)
Reply 3refrigerator keeps food cold by circulating a refrigerant that absorbs heat from interior. when refrigerant is compressed, it releases absorbed warmth outside, allowing interior temperature to drop.
Reply 4tokyo is japan's capital city, bustling with life. it is famous for historic temples, modern fashion, and vibrant culinary scene.
$0.0002 · 17.8s
Nemotron 3.5 Lightning 30B
Kept the rule 3 of 3 times · this answer kept the rule
Reply 1ok
Reply 2mona lisa by leonardo da vinci starry night by vincent van gogh persistence of memory by salvador dali
Reply 3a refrigerator uses coolant to absorb heat from inside space and carry it outside. this process lowers interior temperature and preserves food.
Reply 4tokyo is capital of japan. it is famous for sushi and mount fuji.
$0.0007 · 7.2s
Who made you?
“Which company created you, and what is your model name? Reply in one short sentence.”
GPT OSS 20B
“OpenAI” 3 of 3 times
OpenAI created me, and I’m GPT‑4.
under $0.0001 · 2.6s
Nemotron 3.5 Lightning 30B
“NVIDIA” 3 of 3 times
I'm Nemotron, a language model developed by NVIDIA.
under $0.0001 · 0.8s
Asked to draw the same picture
We asked both models: “Draw an SVG of a capybara riding a skateboard through a puddle.” They had to answer with SVG code alone, with no image tools.
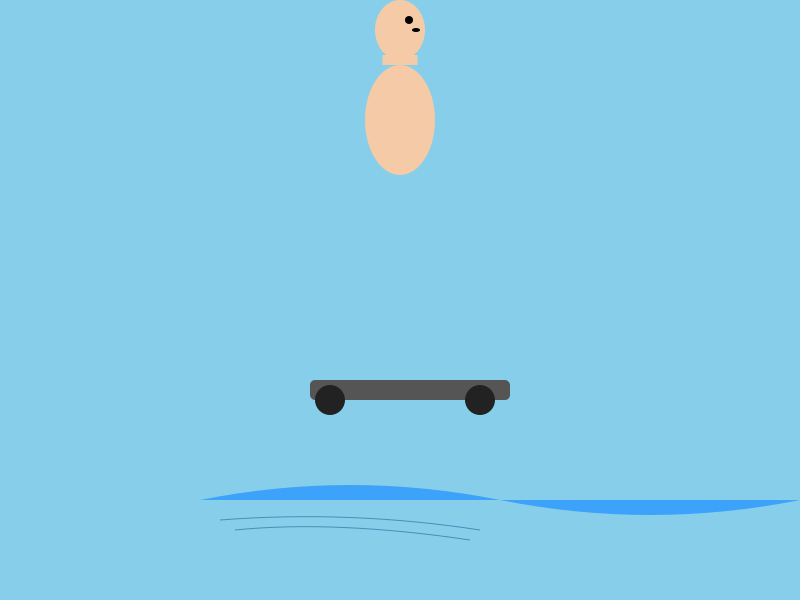
GPT OSS 20B
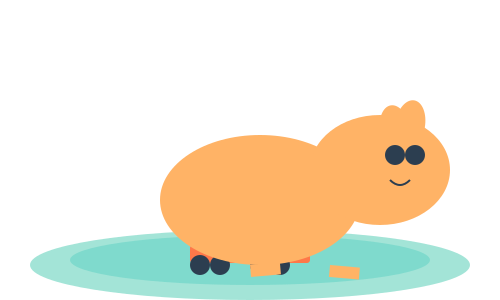
Nemotron 3.5 Lightning 30B
How smart is each one?
Of the 4 scores both models have, Nemotron 3.5 Lightning 30B is ahead on every one.
Every intelligence score we have
Out of 100, higher is better. GPT OSS 20B Nemotron 3.5 Lightning 30B
Overall
Intelligence Index
1012.9
By area
Coding
26.8GPT OSS 20B: not scored yet
Math
62.3Nemotron 3.5 Lightning 30B: not scored yet
Agentic work
3.5GPT OSS 20B: not scored yet
By field of work
Finance & accounting
12.2GPT OSS 20B: not scored yet
Legal
15.5GPT OSS 20B: not scored yet
Healthcare & medicine
11.7GPT OSS 20B: not scored yet
Economics
22.8GPT OSS 20B: not scored yet
Engineering
18.1GPT OSS 20B: not scored yet
Strategy & operations
6.9GPT OSS 20B: not scored yet
Benchmarks
Hard reasoning · Humanity's Last Exam
5.310.6Science · GPQA Diamond
61.174.3Knowledge · MMLU-Pro
71.8Nemotron 3.5 Lightning 30B: not scored yet
Competitive coding · LiveCodeBench
65.2Nemotron 3.5 Lightning 30B: not scored yet
Scientific coding · SciCode
32.1GPT OSS 20B: not scored yet
Terminal tasks · Terminal-Bench 4.0
0.5GPT OSS 20B: not scored yet
Tool use · τ-Bench Banking
8.9GPT OSS 20B: not scored yet
Instruction following · IFBench
57.8Nemotron 3.5 Lightning 30B: not scored yet
Long documents · AA-LCR
3160.3Competition math · AIME 2025
62.3Nemotron 3.5 Lightning 30B: not scored yet
Uncensored · UGI
12.4Nemotron 3.5 Lightning 30B: not scored yet
The specs
| Spec | GPT OSS 20B | Nemotron 3.5 Lightning 30B |
|---|---|---|
| Input price | $0.03 per 1M | $0.05 per 1M |
| Output price | $0.14 per 1M | $0.20 per 1M |
| Cost per test task | Not tested | Not tested |
| Context window | 131K | 262K |
| Max output | 8K | 131K |
| Accepts | Text | Text |
| Open weights | Yes | Yes |
| Lab | OpenAI | NVIDIA |
| Released | Aug 2025 | Aug 2026 |
| Knowledge cutoff | Jun 2024 | Sep 2025 |
Blended price weighs 3 parts input to 1 part output. List prices from models.dev.
Questions
Is GPT OSS 20B or Nemotron 3.5 Lightning 30B cheaper?
GPT OSS 20B is cheaper. It charges $0.03 per 1M input tokens and $0.14 per 1M output tokens, against $0.05 and $0.20 for Nemotron 3.5 Lightning 30B. Blended 3 parts input to 1 part output, that is $0.06 against $0.09 per 1M tokens.
Are GPT OSS 20B and Nemotron 3.5 Lightning 30B open source?
Both are open-weights models: OpenAI and NVIDIA publish the weights, so you can download them and run them on your own hardware, or call them through any host's API. Check each model's license before you ship it.
Which is smarter, GPT OSS 20B or Nemotron 3.5 Lightning 30B?
Nemotron 3.5 Lightning 30B scores higher on the Artificial Analysis Intelligence Index, 12.9 against 10 for GPT OSS 20B. The biggest differences are on AA-LCR (31 vs 60.3) and GPQA Diamond (61.1 vs 74.3).
Which has the longer context window?
Nemotron 3.5 Lightning 30B accepts 262K tokens, against 131K for GPT OSS 20B.
Can I compare GPT OSS 20B and Nemotron 3.5 Lightning 30B on my own prompt?
Yes. ModelCompare sends one prompt to both models at once and shows each answer side by side with what it cost. You can try it free without an account.
Related comparisons
Where the numbers come from
Intelligence Index and benchmark scores are from Artificial Analysis, at each model’s highest effort, except SimpleQA, which is from Epoch AI, and the Uncensored score, which is from the UGI Leaderboard. The hallucination test is ours: questions with one exact answer, fake evidence pushed against right answers and requests that tempt a model to name packages that don’t exist. Prices are list prices from models.dev. Example answers come from our own test runs. Updated October 26, 2026.